Featured
October 20, 2026
Spark Data Skew: How to Detect and Fix It
Why a few oversized partitions can slow an entire Spark job, how to spot skew in the Spark UI, and the techniques that fix it.
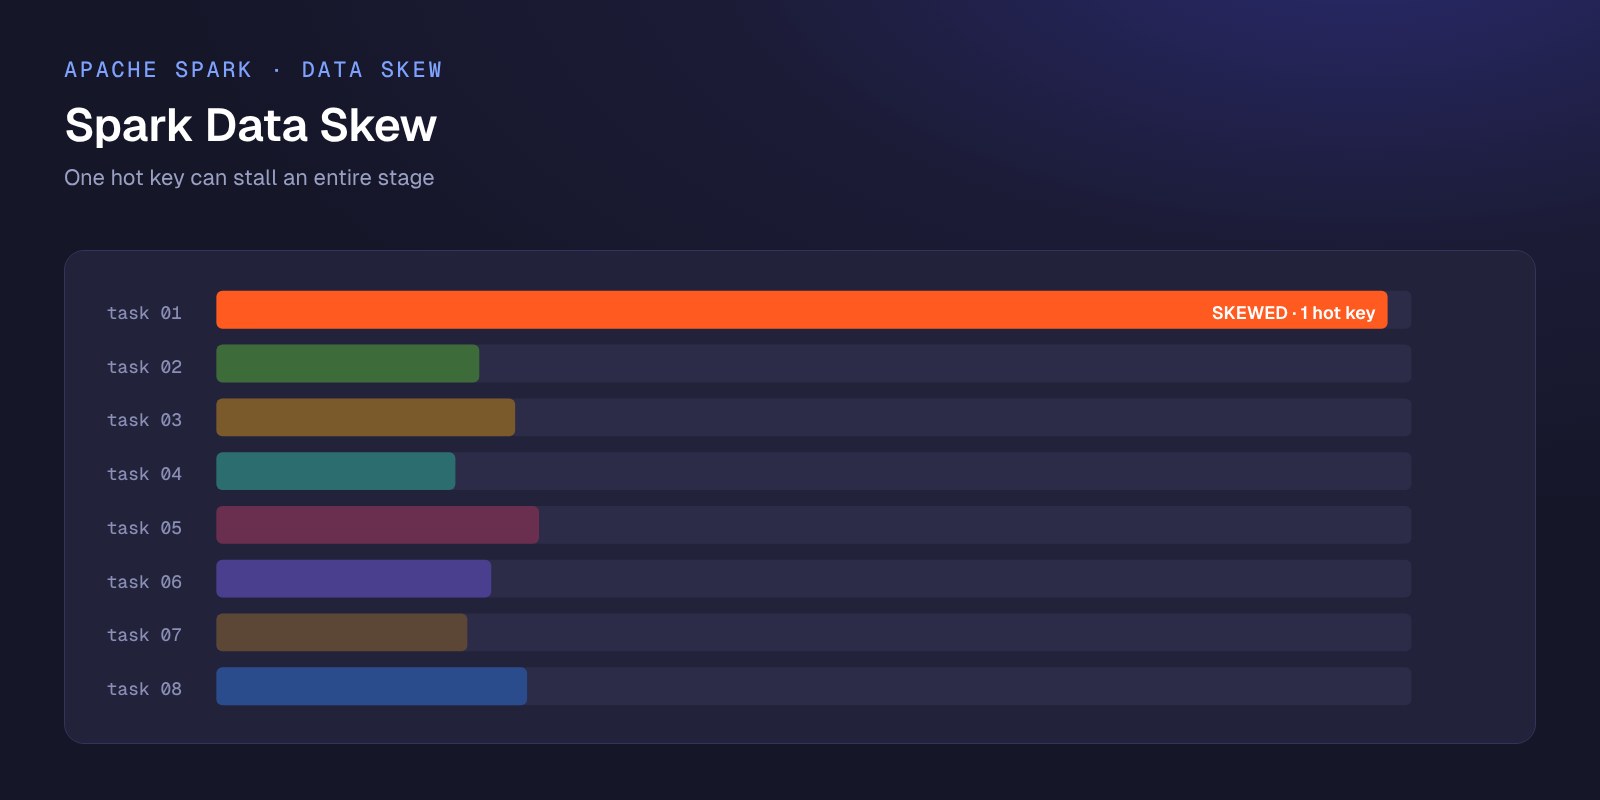
Everything you need to run Apache Spark faster and cheaper: execution internals, data skew, shuffle tuning, cluster sizing and hardware acceleration.
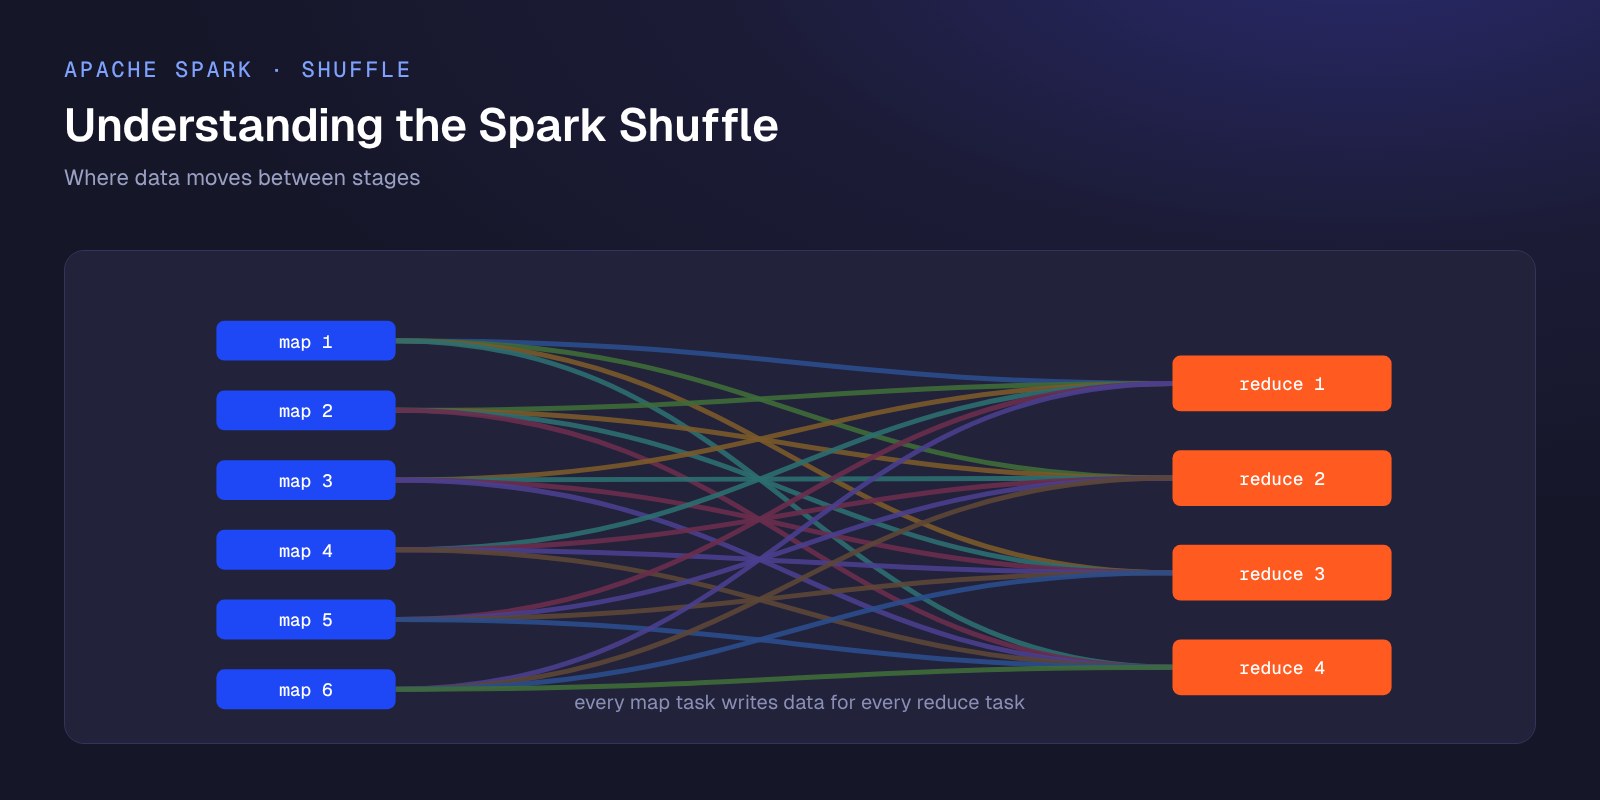
What happens during a Spark shuffle, why it is often the most expensive part of a job, and the settings that make it cheaper.
Why a few oversized partitions can slow an entire Spark job, how to spot skew in the Spark UI, and the techniques that fix it.
Apache Spark is a distributed engine for large-scale data processing, used for ETL, analytics, streaming and machine learning workloads.
Common causes are data skew, large shuffles, too few or too many partitions, and undersized executors. The Spark UI stage view usually shows which one applies.
No. DualBird is designed to accelerate existing Spark workloads without code changes.
Zero risk, zero effort, incredible results.