Mission-focused hardware for big data processing, available on AWS
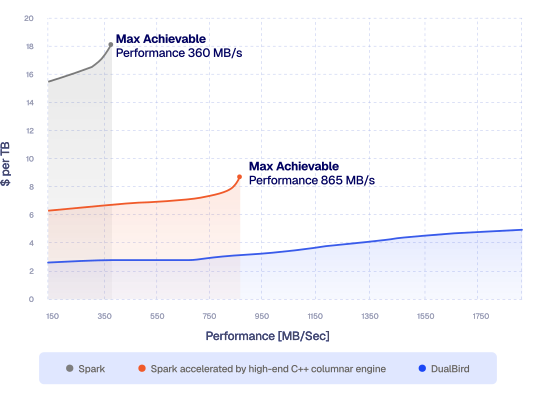
100GB Sort-Based Iceberg Compaction
EC2 Cost
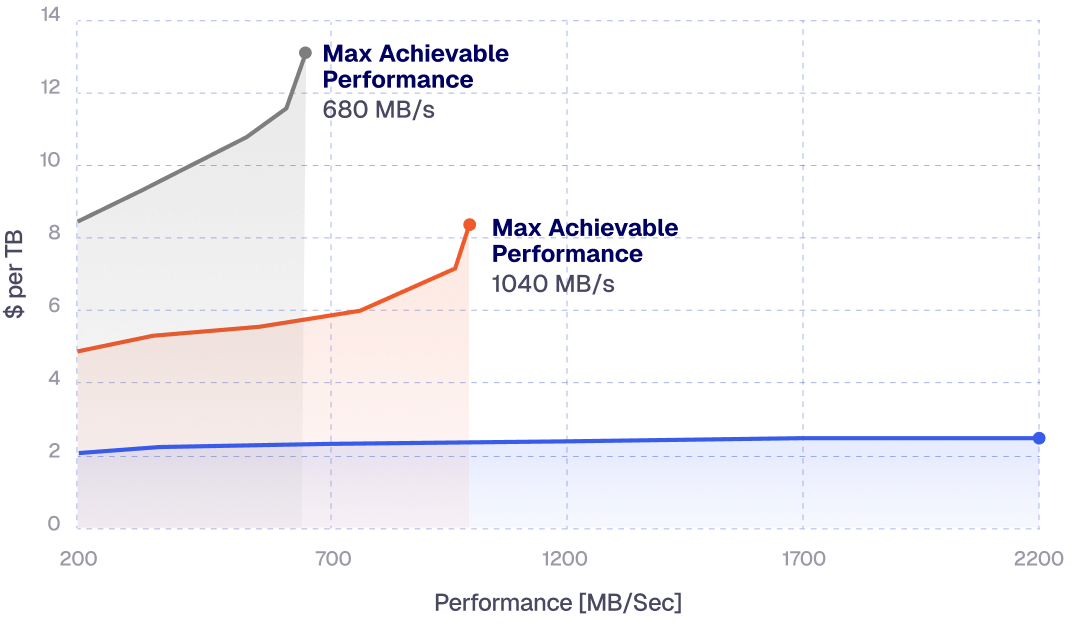

100GB Sort-Based Iceberg Compaction
Single Task Performance
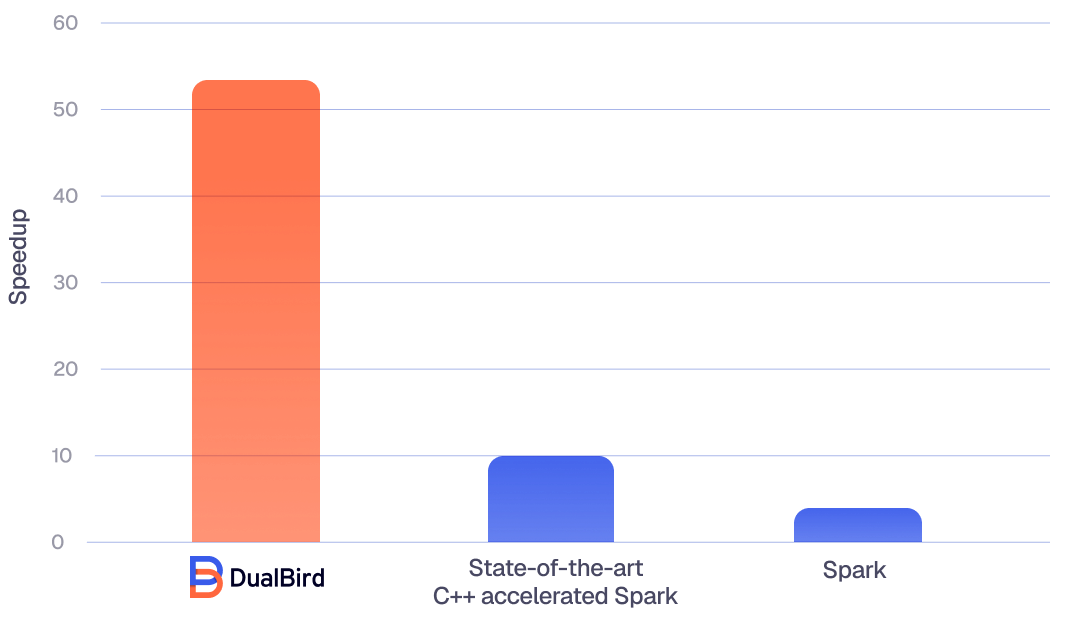
110GB Enrichment Pipeline
(JOIN Denormalization) EC2 Cost
Effortless Onboarding
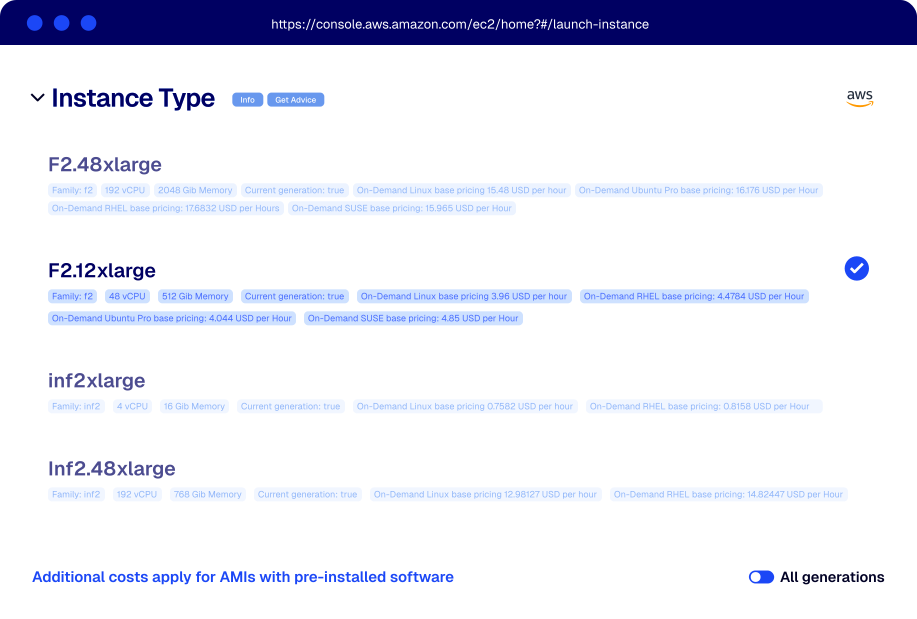
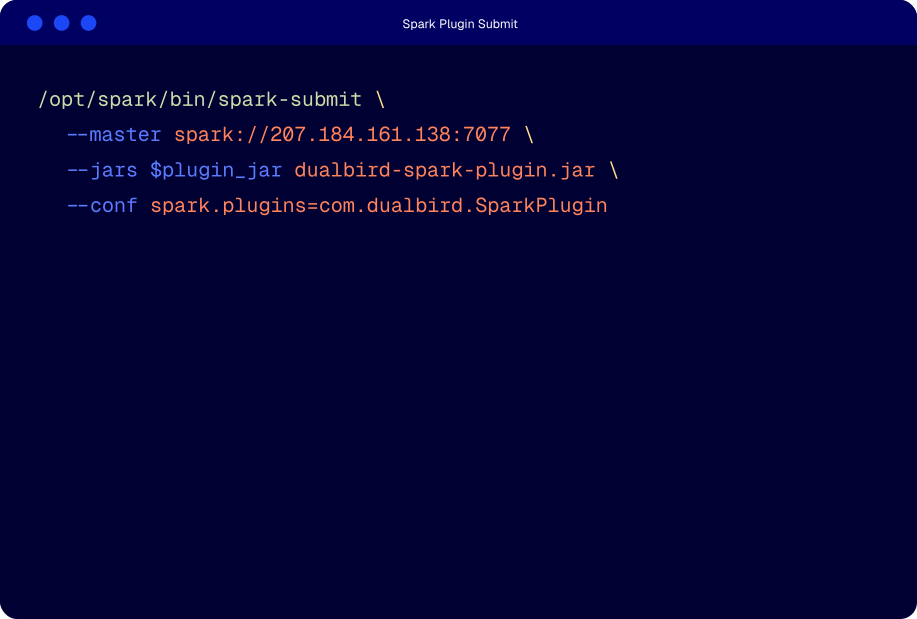
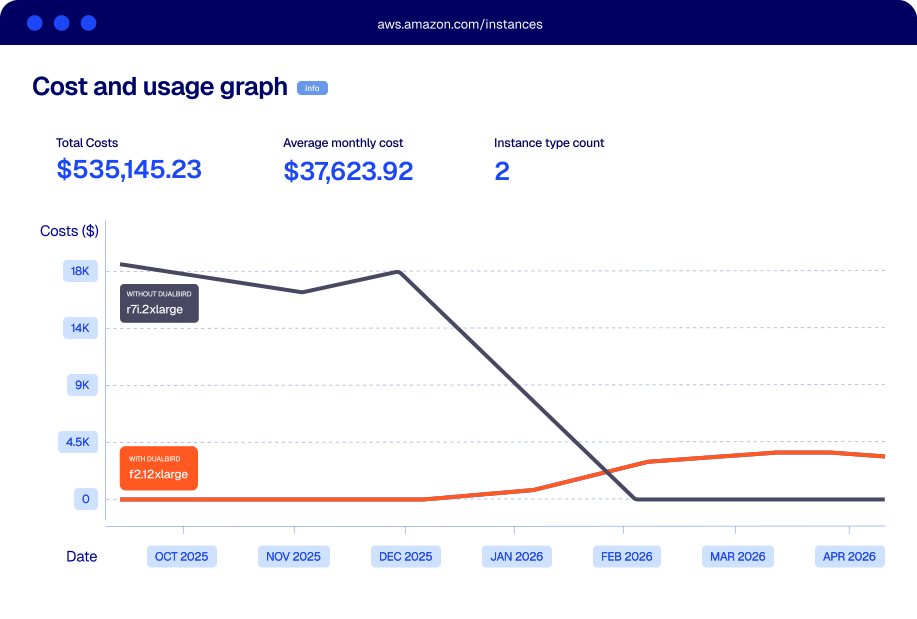
Everything you need to transform your data operations
Improve performance, save time and reduce overhead.
Game-changing speed
Overcome the performance limitations of the classic task-per-core architecture of CPU-based Spark.
Always optimized
The majority of common Spark performance configurations simply do not exist when using our solution, providing best out-of-the-box performance and freeing you from constant tuning and calibration.
Scale up effortlessly
Handle growing data demands without having to update your tech stack.
Eliminate disk spills and data skew issues
Plan ahead better, avoid surprises.
Reduce shuffle data
Speed up your workflows by minimizing excessive data transfers.
Consistent and predictable pipeline cost and run time
Our system is invariant to data properties the CPU-based systems are sensitive to (e.g. high cardinality, high number of columns, etc), making it robust to changes and far more predictable.
Your data, running on your servers.
No compromises on security or compliance. Everything stays under your control.


Transform your data infrastructure performance with a few clicks
Zero risk, zero effort, incredible results.